A meeting transcription accuracy test should compare every candidate with the same representative audio and a carefully reviewed human reference transcript. Calculate word error rate from substitutions, deletions, and insertions, then score critical errors separately: names, numbers, dates, negation, decisions, and action owners. Add speaker attribution, timestamps, summary errors, processing time, and human review time when those outputs matter. Buyers should freeze normalization rules and service settings before comparison. This produces evidence for the actual meeting workflow without accepting a vendor’s headline percentage or assuming that quiet-room performance predicts results with distance, accents, background noise, and overlapping speech.
What Buyers Should Know
- Use acoustically representative meeting audio, not a clean promotional sample.
- Create one human-reviewed reference transcript before comparing candidates.
- Apply the same spelling, punctuation, number, and filler-word rules to every output.
- Measure WER and critical business errors as separate results.
- Test speaker attribution and summaries independently from transcript wording.
- Record the service, model, language, settings, account tier, and test date.
Define accuracy before comparing services
“Accuracy” can refer to several different outcomes. One service may recognize most words while assigning them to the wrong person. Another may produce an acceptable transcript but an incorrect summary. A third may require so much correction that its numerical score does not translate into a useful workflow.
Define the required outputs first:
| Output | Evaluation question | Example failure |
|---|---|---|
| Transcript words | Does the text match the spoken words under fixed rules? | Missing or substituted phrase |
| Critical details | Are names, quantities, dates, decisions, and negation correct? | “15” becomes “50” |
| Speaker attribution | Are words assigned to the correct participant? | Decision credited to the wrong person |
| Timestamps | Can a reviewer locate the source passage? | Timestamp points to a different section |
| Summary | Does it preserve material facts and omit unsupported claims? | New action item invented |
| Review workload | How long does approval take? | Excessive listening and correction |
Microsoft’s speech evaluation documentation defines word error rate through insertion, deletion, and substitution errors compared with a human-labeled transcript. Google Cloud’s accuracy guide likewise uses acoustically representative audio and ground-truth text when evaluating recognition.
WER is valuable because it creates a repeatable lexical comparison. It is not a complete measure of meeting usefulness. A wrong customer name or reversed negative can matter more than several harmless filler-word differences.
Create a controlled human reference transcript
The reference transcript is the comparison standard, so inconsistency in that file weakens every score. Use a reviewer who can hear the recording clearly and resolve names or specialized terms with appropriate source material.
Before transcription, write a normalization guide covering:
- Whether filler words such as “um” and “uh” are included.
- Whether contractions are expanded.
- How spoken numbers, currency, dates, and abbreviations are written.
- How punctuation and capitalization are treated.
- How partial words, false starts, and unintelligible segments are marked.
- Whether speaker labels and timestamps are evaluated separately.
Use at least one second reviewer for ambiguous or high-impact passages. Freeze the final reference before generating comparative scores. If the reference changes, rerun every candidate against the same version.
The NIST Rich Transcription evaluation program treated meeting speech-to-text, speaker diarization, and speaker-attributed transcription as related but distinct tasks. Its historical benchmark results should not be used as a current MG6 target. The evaluation design remains useful because it shows why meeting speech and speaker attribution require explicit test conditions.
Build a six-case meeting test set
One file cannot represent a business’s full workload. Use a compact set that exposes different failure modes while remaining practical to review.
| Test case | Include | Purpose |
|---|---|---|
| Quiet two-person discussion | Normal pace and familiar terms | Establish a controlled baseline |
| Multi-speaker meeting | Several turns and similar voices | Test speaker changes and attribution |
| Distant-speaker segment | Normal speech from a far seat | Expose weak source-audio conditions |
| Background-noise segment | HVAC, typing, or paper movement | Test realistic steady and intermittent noise |
| Critical-details script | Names, codes, dates, quantities, and negation | Measure errors with business impact |
| Short overlap segment | Two speakers talking simultaneously | Reveal limitations hidden by turn-taking samples |
Use real or properly authorized audio that reflects the intended deployment. Remove or protect sensitive information according to company policy. Keep each source file, reference transcript, and output under a stable test ID.
IBM’s speech-to-text overview distinguishes synchronous, asynchronous, and streaming recognition scenarios. If candidates use different modes, record that fact rather than treating the outputs as identical implementations. The AWS speech-to-text overview also notes that audio quality and background conditions influence recognition, supporting the use of varied meeting cases.
Calculate WER and classify critical errors
Word error rate uses the following structure:
WER = (substitutions + deletions + insertions) ÷ words in the reference transcript
Keep the raw counts as well as the percentage. Two outputs can have the same WER while failing in different ways. Deletions may hide missing speech; insertions can add words that were not spoken; substitutions can corrupt names or decisions.
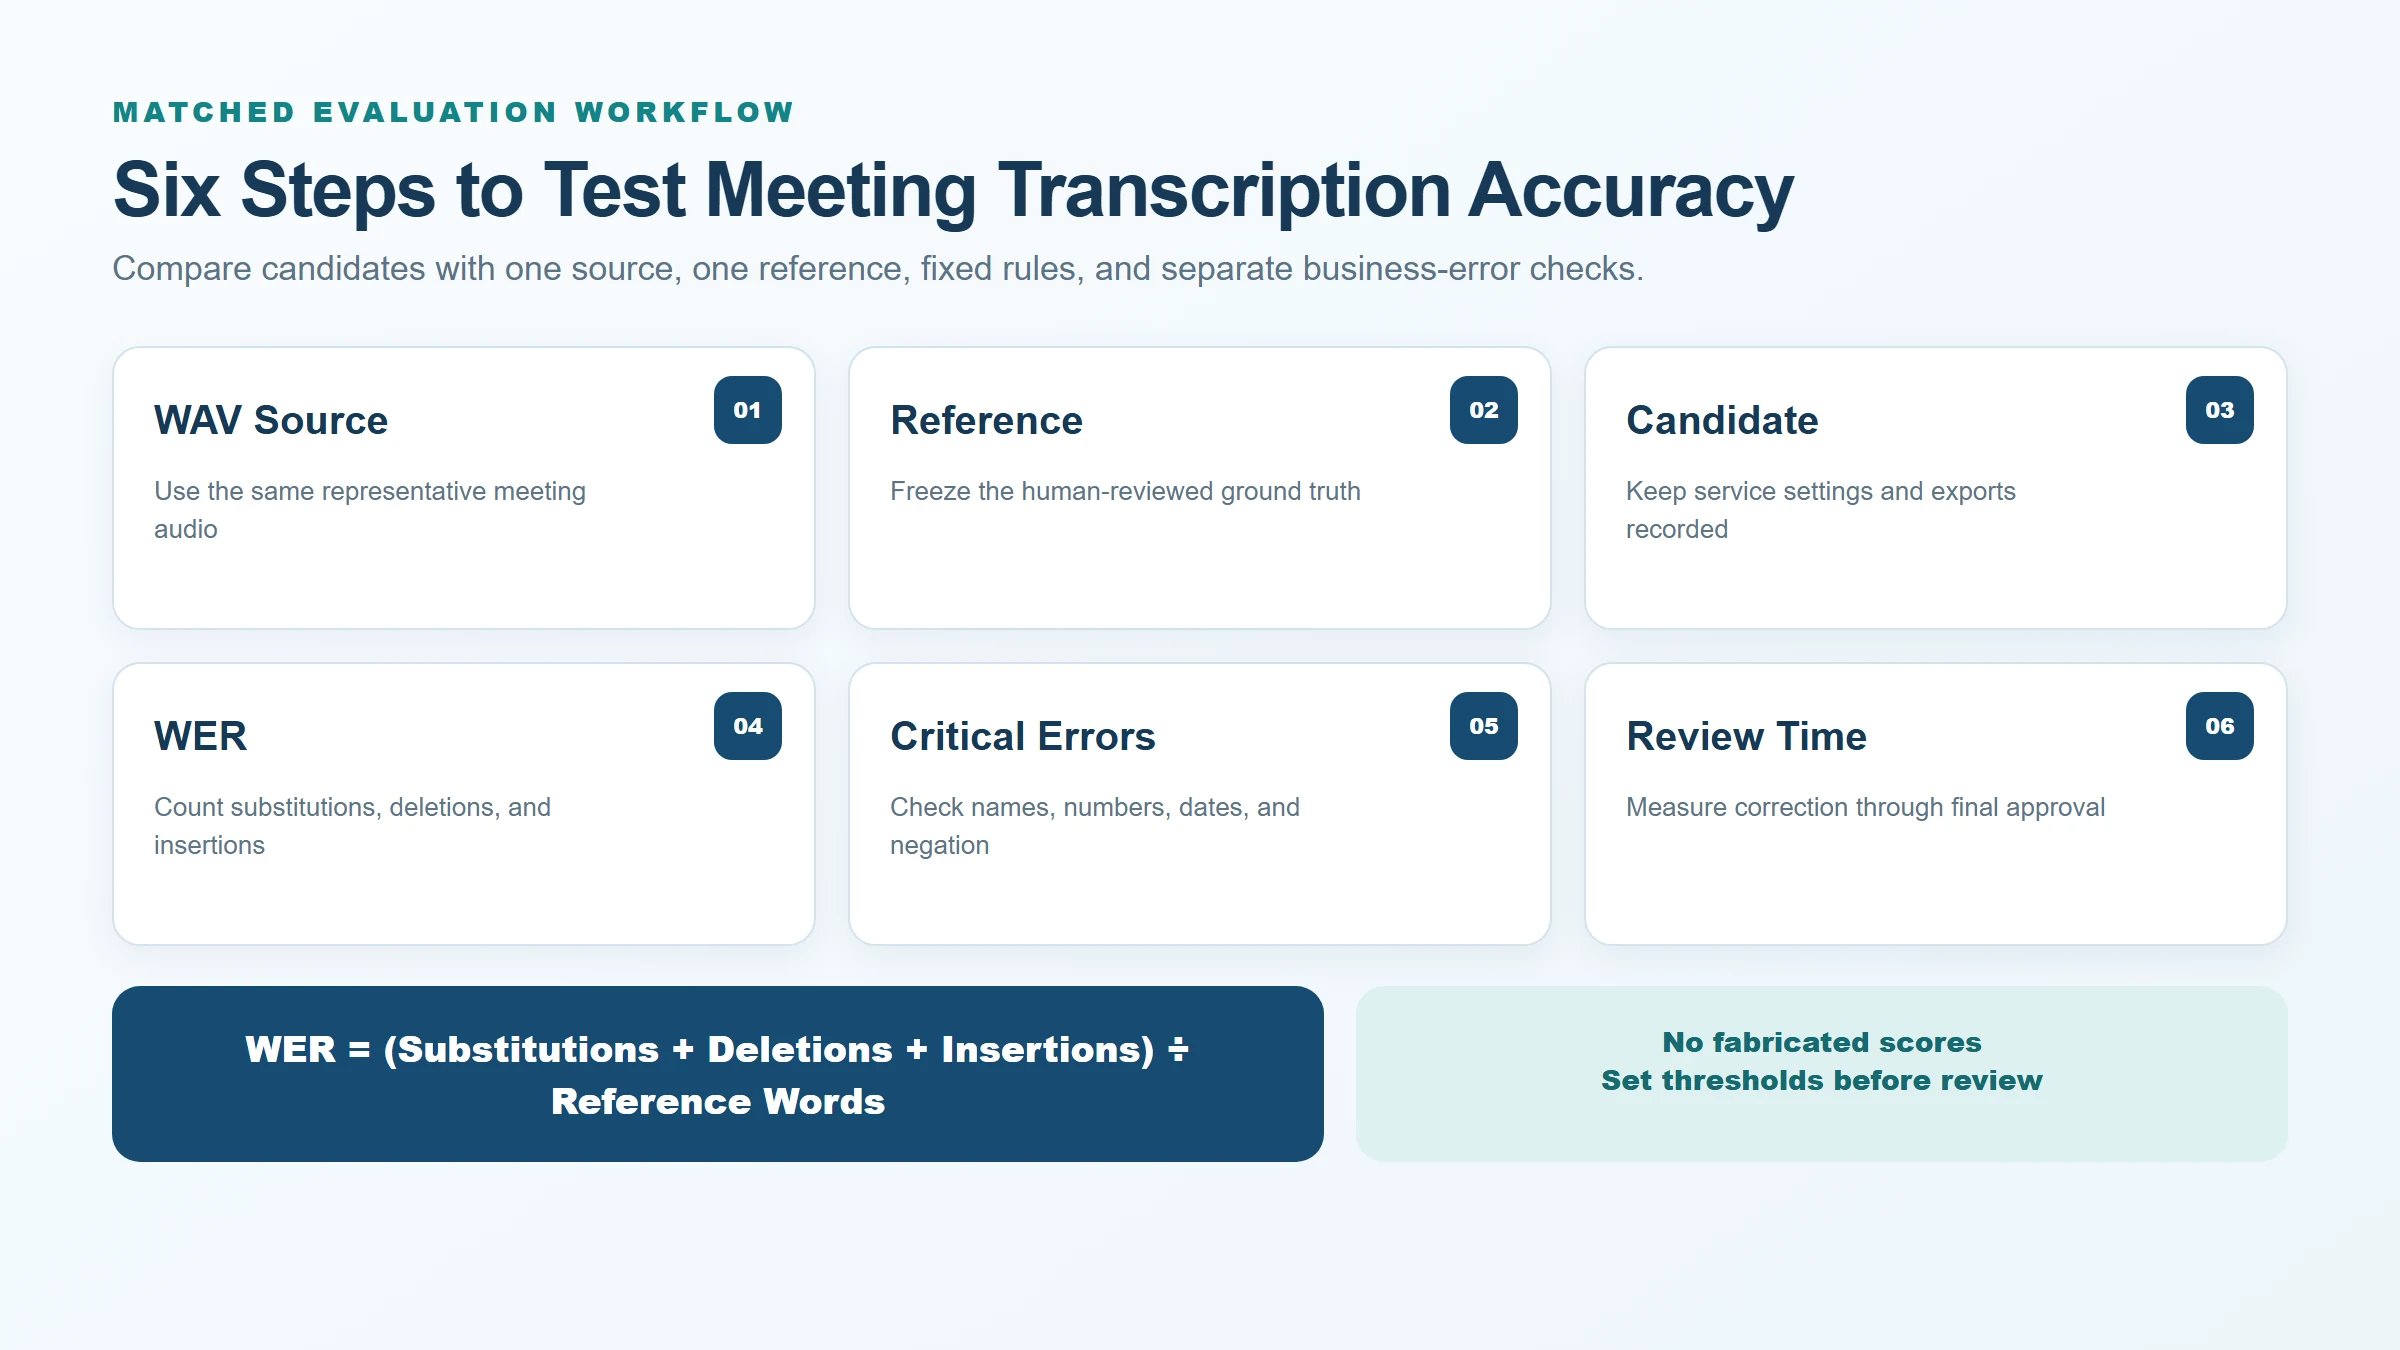
After calculating WER, perform a critical-error pass:
- Mark every person, company, product, and place name.
- Mark quantities, money, percentages, dates, times, and identifiers.
- Mark negative expressions such as “not,” “cannot,” and “do not approve.”
- Mark decisions, assigned owners, deadlines, and commitments.
- Classify each issue as correct, minor, material, or unresolved.
Do not combine all critical errors into WER without explanation. Report both results. A candidate with a slightly higher WER may still be preferable if it preserves the details the organization cares about and requires less review.
Measure speaker, summary, and review failures separately
Speaker labeling should be evaluated only when the candidate service offers it. Check speaker changes, incorrect assignments, unknown-speaker segments, and failures during overlap. Do not infer MG6 speaker diarization from its microphones or connected transcription capability.
Summaries require a source-grounded review. For each statement, classify it as:
- Supported by the reviewed transcript.
- Correct but missing material context.
- Unsupported or invented.
- Assigned to the wrong person.
- Missing from the summary despite being required.
Measure human review time from opening the candidate output to approval. Include listening, searching, correcting, relabeling speakers, and repairing the export. Review time often determines whether a numerically accurate transcript is operationally useful.
If timestamps or speaker labels must survive export, open the exported file outside the service and verify them. The comparison should use the same required output format for every candidate.
Control the input and configuration
A fair comparison holds source audio and evaluation rules constant. Record differences that cannot be held constant.
| Control | What to record |
|---|---|
| Audio | File hash or stable ID, duration, format, channels, and recording condition |
| Service | Provider, product, model if disclosed, and processing mode |
| Settings | Language, vocabulary hints, speaker options, and formatting choices |
| Account | Plan or tier, permissions, and relevant usage limits |
| Output | Export format, timestamps, speaker labels, and correction state |
| Review | Reference version, scoring script or method, reviewer, and date |
Avoid comparing a corrected transcript from one service with an untouched transcript from another. Avoid changing vocabulary hints halfway through a test without creating a new configuration ID. Retest after material application, service, model, or firmware changes.
Where This Product Fits
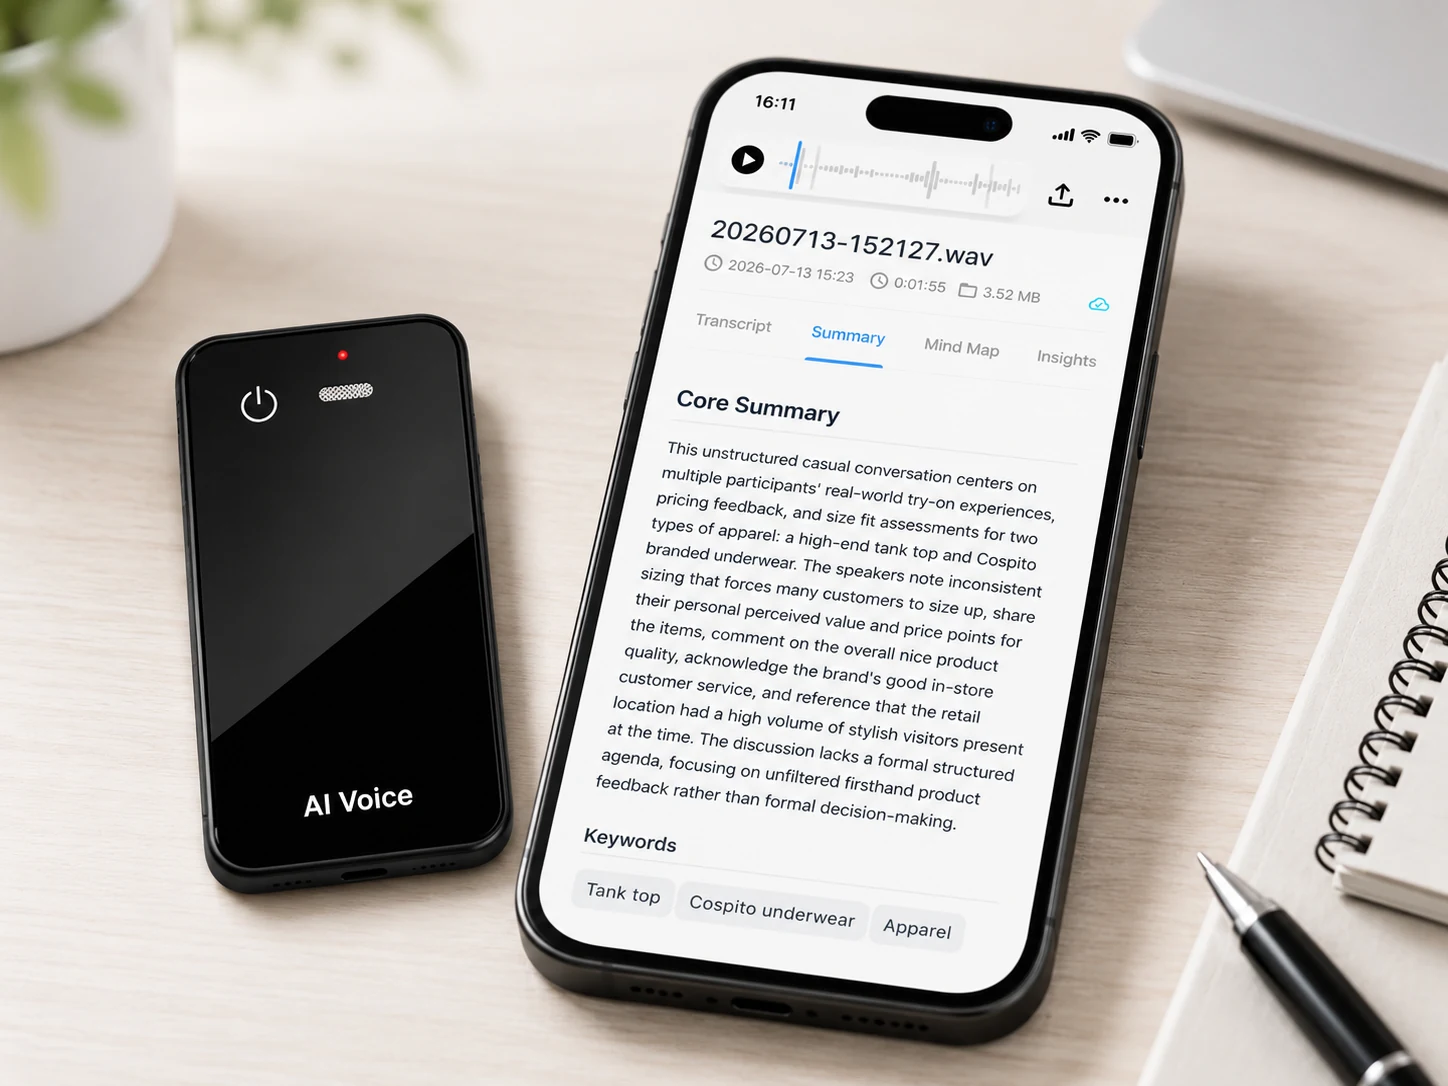
The MG6 AI Recording Card can provide an offline WAV source file for a matched transcription evaluation. Connected project services can support transcription, real-time translation, summaries, and mind maps. The exact provider, language coverage, allowance, output, and software scope require written confirmation.
| Test component | Confirmed MG6 reference scope | Evaluation boundary |
|---|---|---|
| Source audio | Offline WAV recording | Inspect file quality before scoring text |
| Transfer and processing | Connected workflow depends on project configuration | Record the exact app, service, account, and settings |
| AI outputs | Connected services can support transcript and derivative outputs | Test only the outputs included in the proposed scope |
| Accuracy claim | No verified public MG6 WER or matched result | Publish the method or actual approved evidence, not an invented score |
MG6’s role in this article is the source-to-review workflow. The article does not claim a WER, universal accuracy percentage, speaker-attribution feature, or service ranking. Buyers should preserve the same WAV files so shortlisted services can be compared and later changes can be retested.
For broader selection criteria, use the voice recorder with transcription buyer guide. The distinction between offline recording and offline AI transcription also prevents local capture from being misreported as local speech processing.
Use a blank acceptance scorecard
Set thresholds before viewing candidate results. The organization should choose them according to the risk and workload of the intended use; this article does not prescribe a universal passing percentage.
| Metric | Weight | Threshold | Candidate result | Pass / Review |
|---|---|---|---|---|
| WER | ___ | ___ | ___ | ___ |
| Critical names and terms | ___ | ___ | ___ | ___ |
| Numbers, dates, and negation | ___ | ___ | ___ | ___ |
| Speaker attribution | ___ | ___ | ___ | ___ |
| Summary support | ___ | ___ | ___ | ___ |
| Human review time | ___ | ___ | ___ | ___ |
| Export continuity | ___ | ___ | ___ | ___ |
Attach the source file, reference version, raw error counts, marked transcript, summary review, exported file, and reviewer notes. A percentage without those artifacts is difficult to reproduce or audit.
FAQ
What is word error rate?
WER compares a candidate transcript with a human-reviewed reference. It divides substitutions, deletions, and insertions by the number of words in the reference. A lower value indicates fewer word-level differences under the chosen normalization rules, but it does not measure every business-critical failure.
How should names and numbers be scored?
Track them in a separate critical-error category. Count whether each required name, identifier, quantity, date, amount, and negative statement is correct. Document minor formatting differences separately from errors that change meaning.
Does quiet-room accuracy predict meeting performance?
It provides a baseline but does not represent distance, echo, HVAC noise, accents, multiple speakers, or overlapping speech. Include representative meeting cases and keep the source audio identical across candidates.
How many samples are enough?
There is no universal number. Start with a compact set covering the main acoustic and language conditions, then add cases until results are stable enough for the decision’s risk. Preserve every test ID and avoid presenting a small pilot as universal performance.
Should summary errors be scored separately?
Yes. A transcript and a summary are different outputs. Check whether each summary statement is supported, correctly attributed, sufficiently contextualized, and free of invented decisions or actions. Keep that score separate from WER.
Request an MG6 matched sample evaluation
Use one approved WAV test set, a frozen reference transcript, and the blank scorecard to compare the proposed MG6 connected workflow. Contact Yosiya to request an MG6 sample and confirm the recording, transfer, AI service, export, and evaluation scope.